Next: Grid-based Methods Up: Fundamentals of Computer Vision Previous: Elements of Probability
This chapter discusses the problem of statistical filtering, namely, the class of problems in which data from one or more noisy sensors are available. These data represent observations of the dynamic state of a system that cannot be observed directly but must be estimated. The procedure used to obtain the best estimate of a system's internal state is called “filtering”, since it removes the various noise components. The evolution of a system (that is, the evolution of its internal state) must follow known physical laws, which are affected by a noise component (process noise). Knowledge of the equations governing the evolution of the state makes it possible to obtain a better estimate of the internal state.
A physical process can be represented in state space (State Space Model) by a function describing how the state  evolves over time:
 |
(3.1) |
 denotes any known system inputs, and
 denotes the parameter representing the process noise, that is, the randomness governing the evolution.
Likewise, the observation of the state is a process affected by noise, in this case called observation noise.
Here too, it is possible to define a function modeling the observation
 as
 |
(3.2) |
 is observation noise and a function only of the current state.
This formalism is described in the continuous-time domain.
In practical applications, signals are sampled at discrete times  , and a discrete-time version is therefore normally used in the form
 and
 can be regarded as white-noise sequences with known statistics.
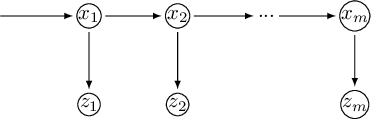
In systems satisfying equations (3.3), state evolution depends only on the previous state, whereas observation depends only on the current state (Figure 3.1). If a system satisfies these assumptions, the process is said to be Markovian: the evolution and observation of the system depend only on the current state and not on past states. Access to information about the state always occurs indirectly through observation (Hidden Markov Model).
Many approaches for estimating the unknown state of a system from a set of measurements do not account for the noisy nature of these observations. It is possible to construct an algorithm that performs nonlinear regression on the observations to estimate all the states in the problem by solving an optimization problem with a large number of unknowns.
Unlike regression methods, filters aim to provide the best estimate of the state variables as observation data become available. From a theoretical standpoint, regression provides the optimal result, whereas filtering converges to the correct result only after a sufficiently large number of samples.
Bayesian filters aim to estimate, at the discrete time instant , the state of the random variable
 given an indirect observation of the system,
 .
Filtering techniques provide both the best estimate of the unknown state  and the multivariate probability distribution
 representing the available knowledge of the state itself.
Given an observation of the system, it is possible to define a probability density for a posteriori of observing the event
 , based precisely on the additional information provided by that observation:
 denotes the probability that the hidden state is given the observation
 .
The “function”
represents the state measurement model (measurement model).
In the literature, the posterior distribution
 is also referred to as the belief.
Applying Bayes' theorem to equation (3.4) yields
 |
(3.5) |
 is the normalization factor such that
 .
Knowledge of
 is essential; it represents the probability that the observation is precisely the quantity observed given the possible state .
The use of Bayes' theorem to estimate the state given the observation is why this class of filters is called Bayesian.
In addition to the a posteriori knowledge of the probability distribution, further information can be used to improve the estimate: knowledge a priori of the observation, obtained from the constraint that the state does not evolve in a completely unpredictable manner but can instead evolve only in certain ways with certain probabilities. These possible modes of system evolution depend only on the current state.
The Markov process assumption implies that the only past state affecting the evolution of the system is the state at time  , namely,
 .
It is therefore possible to perform an a priori prediction using the Chapman–Kolmogorov equation:
 |
(3.6) |
 represents the system dynamics (dynamic model) and
 denotes any inputs that influence the evolution of the system and are known completely.
Given the a priori state estimate and the observation  , equation (3.4) can be rewritten as the state update equation
The state is estimated by alternating a prediction phase (a priori estimation) with an observation phase (a posteriori estimation). This iterative process is called recursive Bayesian estimation (Recursive Bayesian Estimation).
The techniques described in this section use only the latest available observation to estimate the state. Formally, the discussion can be extended to the case in which all observations are used to obtain a more accurate state estimate.
In this case, the filtering and prediction equations become
 |
(3.8) |
Since continuous variables are being estimated, Bayesian theory cannot be used “directly”. Several approaches have therefore been proposed in the literature to enable efficient estimation, both computationally and in terms of memory usage.
Depending on whether the problem is linear or nonlinear and whether the noise probability distribution is Gaussian or non-Gaussian, each of these filters performs more or less optimally.
The Kalman filter (Section 3.2) is optimal when the problem is linear and the noise distribution is Gaussian. The Extended Kalman and Sigma-Point Kalman filters, Sections 3.4 and 3.5, respectively, are suboptimal filters for nonlinear problems with Gaussian noise distributions (or distributions close to Gaussian). Finally, particle filters are a suboptimal solution for nonlinear problems with non-Gaussian noise distributions.
Grid-based filters (Section 3.1) and particle filters (Section 3.8) operate on a discrete representation of the state, whereas Kalman, Extended Kalman, and Sigma-Point filters operate on a continuous representation of the state.
Kalman, Extended Kalman, and Sigma-Point Kalman filters estimate the uncertainty distribution (of the state, process, or observation) as a single Gaussian. Multimodal extensions such as Multi-hypothesis tracking (MHT) make it possible to apply Kalman filters to distributions such as Gaussian mixtures, whereas particle and grid-based filters are inherently multimodal.
An excellent survey of Bayesian filtering is (Che03).