


Next: Soft Margin SVM Up: Classification Previous: Logistic Regression
|
Both LDA and logistic regression lead to a linear decision boundary. However, the criteria used to determine this boundary are fundamentally different.
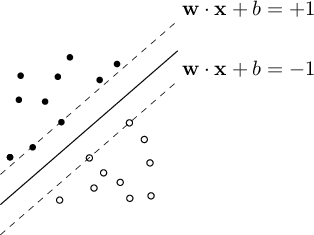
SVM (CV95), like LDA and logistic regression, produces a linear classifier based on a discriminant function of the form shown in equation (5.5). However, the approach is different. The goal of SVM is to determine, among all hyperplanes that correctly separate the two classes, the one that maximizes the separation margin between the training examples and the decision boundary (decision boundary). The idea underlying this approach is that a wider margin generally leads to better classifier generalization and greater robustness to variations in the data.
Let the classification classes be defined as the typical classes of a binary problem in the form
 , and consider the hyperplane of formula (5.4).
Suppose that there exist optimal parameters
 satisfying the constraint
 sample provided during the training phase.
It can be assumed that, for each category, one or more vectors  exist for which constraint (5.27) is satisfied with equality. These elements are called Support Vectors. They are the samples that determine the separation margin and, as will be shown later through the KKT conditions, are the only samples associated with nonzero Lagrange multipliers.
The point-to-plane distance  (cf. Eq. (1.88)) is
To maximize the margin in equation (5.29), its inverse must be minimized, namely
This class of problems (minimization with inequality constraints, or the primal optimization problem) is solved using the Karush-Kuhn-Tucker approach, which is the method of Lagrange multipliers generalized to inequalities.
Using the KKT conditions, the Lagrangian function is obtained:
 and
 and maximized with respect to
 . The weights
 are the Lagrange multipliers.
Setting the partial derivatives to zero gives
 and
 .
The maximum of function
 computed over
gives the
 associated with each training vector .
This maximum makes it possible to find the solution to the original problem.
The KKT conditions hold for this relation, among which the constraint known as Complementary slackness is particularly important:
and the constraint violation must be zero. In particular,
 |
(5.36) |
 and do not contribute directly to the solution.
By solving the quadratic problem (5.34), subject to constraint (5.32) and
, the weights having
 will be the Support Vectors.
Substituting these weights into equations (5.33) and (5.35) yields the maximum-margin hyperplane.
The most widely used method for solving this QP is Sequential Minimal Optimization (SMO). For an in-depth treatment of topics related to SVMs, see (SS02).


