Next: Activation Functions Up: Classification Previous: AdaBoost and its variants
Ensemble Learning techniques construct complex models by combining several relatively simple classifiers. Neural networks follow a different philosophy: instead of combining independent classifiers, they construct a single parametric model capable of simultaneously learning a representation of the data and the classification function.
Research in Machine Learning (and, more generally, Computer Vision) has always sought inspiration from the human brain for the development of algorithms.
Artificial neural networks (artificial neural networks, ANN) are based on the concept of an “artificial neuron,” that is, a structure that, similarly to the neurons of living organisms, applies a nonlinear transformation (called the activation function) to the weighted contributions of the neuron's different inputs:
 |
(5.109) |
 are the various inputs associated with the
 -th neuron, with corresponding weights
 ,
 is the neuron's output, and the strongly nonlinear activation function
 is normally a step, sigmoid, or logistic function.
The bias
 is sometimes simulated by means of a constant input
 .
The simplest neural network, consisting of an input layer and an output layer, is equivalent to the perceptron model (perceptron) introduced by Rosenblatt in 1957. Like the brain of living organisms, an artificial neural network consists of interconnected artificial neurons.
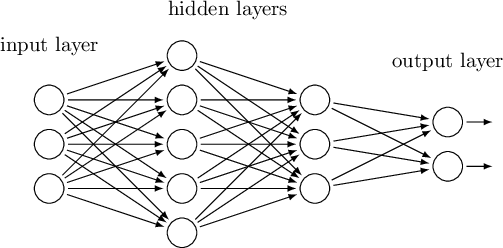
The geometry of a feedforward neural network, the topology normally used in practical applications, is that of a MultiLayer Perceptron (MLP) and consists of multiple hidden layers of neurons connecting the input layer to the output layer, which in turn becomes the input to the next layer.
The training phase consists of estimating the weights  that minimize the error between the training labels and the values predicted by the network
 :
 |
(5.110) |
can be estimated using well-known optimization techniques. Normally, the backpropagation technique is used; this is essentially gradient descent with the chain rule for computing derivatives, since MLPs are layered structures.