Next: M-Estimator Up: Regression and Optimization Methods Previous: Regression to a Conic
There is a family of linear models that relate the dependent variable to the explanatory variables through a nonlinear function, known as generalized linear models (generalized linear model).
Logistic regression belongs to this class of models when the variable  is dichotomous, that is, when it can take only the values
 or
 .
By its nature, this type of problem is particularly important in classification problems.
For binary problems, it is possible to define the probabilities of success and failure:
 |
(4.118) |
The response of a linear predictor of the form
 |
(4.119) |
and and is therefore unsuitable for this purpose.
It is necessary to associate the response of the linear predictor with the response of a function  , a function of the probability
 :
 |
(4.120) |
 , the mean function, is a nonlinear function defined over
 .
must be invertible, and its inverse
 is the link function.
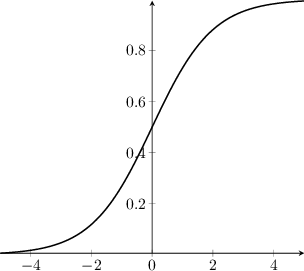
A widely used model for the function is the logit function, defined as:
 , since it represents how many times more likely success is than failure, is called the odds ratio; consequently, function (4.121) represents the logarithm of the probability that an event occurs relative to the probability that the same event does not occur (log-odds).
Its inverse exists and is given by
In this case, the maximum-likelihood method does not coincide with the least-squares method but with
 |
(4.123) |
 |
(4.124) |
 to be estimated.
Paolo medici