Next: Recurrent Neural Networks and Up: Deep Learning Previous: Deep Neural Networks
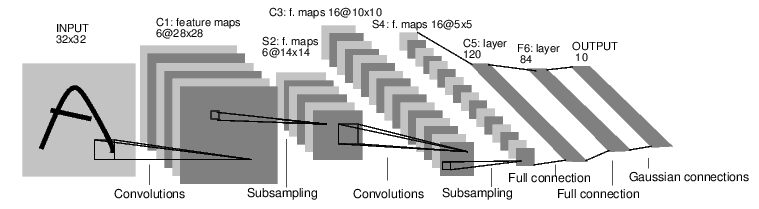
Convolutional Neural Networks (CNNs) represent a natural evolution of deep neural networks for processing spatially structured data, such as images. Unlike conventional MultiLayer Perceptrons (MLPs), CNNs exploit the local correlation of pixels and spatial redundancy through convolutional layers in which the weights are shared. This architecture makes it possible to learn hierarchical, translation-invariant features automatically, significantly reducing the number of parameters to optimize and improving learning efficiency. The following paragraphs describe the main components of a CNN, including convolutional layers, activation functions, pooling, and typical deep-training architectures.
CNNs are multilayer neural networks similar to MultiLayer Perceptrons, but with a distinctive structure: at least one of the layers consists of sets of neurons that share weights, known as convolutional layers (convolutional layer).
In a convolutional layer, the activation of a neuron depends on the dot product between a kernel (or filter) and a local region of the input:
 |
(5.116) |
 represents the filter weights,
 the local portion of the image centered at
 , and
 a possible bias.
Convolution can be applied with strides other than 1, thereby producing a subsampled activation layer relative to the input. Because filters progressively reduce the dimensions of the activation maps, padding is often introduced to keep the output size constant.
The activation maps (activation maps) are transformed by a nonlinear activation function, typically a ReLU. A pooling layer is often then inserted to reduce dimensionality and introduce local invariance: max pooling is the most common choice, while average pooling and L2-norm pooling were more widespread in the past.
CNNs are designed to exploit multichannel, two-dimensional inputs.
A CNN generally takes a third- or fourth-order tensor as input; for example, an image  with 3 channels (R,G,B) is a third-order tensor.
Each convolutional layer can contain
 different kernels, producing output activation maps of size
 .
The architecture of a deep network (Deep Neural Network, DNN) may include:
At the final stage (loss layer), a conventional classification method (MLP, AdaBoost, or SVM) is applied to the reduced representation of the input, preserving most of the useful information.
DNNs are typically trained using variants of stochastic gradient descent (see Section 4.3.3), iteratively optimizing the weights of the filters and fully connected layers based on the classification error.
Paolo medici