Next: Auto-Encoders Up: Deep Learning Previous: Representation Learning
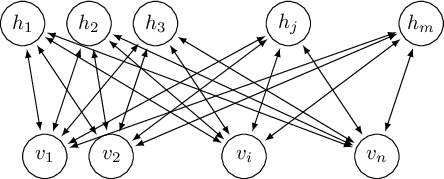
The turning point between shallow and deep training techniques is generally considered to have occurred in 2006, when Hinton and others at the University of Toronto introduced Deep Belief Networks (DBNs) (HOT06), an algorithm that “greedily” trains a layered structure one layer at a time using an unsupervised training algorithm. The distinctive feature of DBNs is that their layers consist of Restricted Boltzmann Machines (RBMs) (FH94,Smo86).
Let
 be a binary stochastic variable associated with the visible state and
 a binary stochastic variable associated with the hidden state.
Given a state
 , the energy of the configuration of the visible and hidden layers is given by (Hop82)
 and
 are the binary states of the visible and hidden layers, respectively, while
 and
 are the weights, and
 are the weights associated with them.
A Boltzmann Machine is similar to a Hopfield network, except that all outputs are stochastic.
A Boltzmann Machine can therefore be defined as a special case of an Ising model, which is itself a special case of a Markov Random Field.
Similarly, RBMs can be interpreted as stochastic neural networks in which the nodes and connections correspond to neurons and synapses, respectively.
The probability of the joint configuration
 is given by the Boltzmann distribution:
 is given by
The word restricted refers to the fact that direct interactions between units belonging to the same layer are not permitted; interactions are allowed only between adjacent layers.
Given an input  , the binary hidden state is activated with probability:
 |
(5.112) |
 is the logistic function
 .
Similarly, the visible state can readily be obtained given the hidden state:
 |
(5.113) |
Estimating the model parameters
so as to correctly model the distribution of the training data is computationally expensive.
However, in 2002 Hinton proposed the Contrastive Divergence (CD) algorithm, which enables much more efficient training of RBMs, finally making them suitable for large-scale applications.
A detailed and practical description of RBM training can be found in (Hin12).
Paolo medici