Next: ADAptive BOOSTing Up: Ensemble Learning Previous: Ensemble Learning
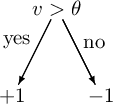
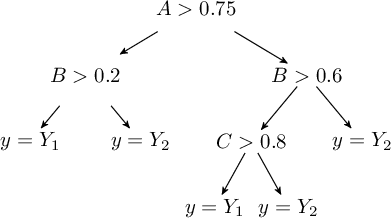
A Decision Tree (Decision Tree) is a very simple and effective method for implementing a classifier, and training decision trees is one of the most successful techniques currently available. A decision tree is a tree of classifiers (Decision Stumps) in which each internal node is associated with a particular “question” about a feature (feature). From this node, as many branches depart as there are possible values that the feature can take, eventually reaching the leaves, which indicate the category associated with the decision. Particular attention is normally paid to binary decision nodes.
A good “question” divides samples from heterogeneous classes into subsets with sufficiently homogeneous labels, stratifying the data so that each stratum contains little variance.
To enable this, it is necessary to define a metric that measures this impurity.
Let  be a subset of samples from a particular training set consisting of
 possible classes.
is in fact a random variable that takes only discrete values (the continuous case is analogous).
Each discrete value
 , which can take , can be associated with the probability distribution
 .
is a data set composed of classes, and
 is the relative frequency of class
 within the set .
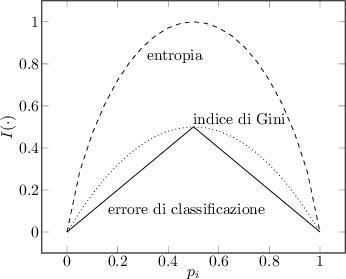
Given the definition of , the following metrics are widely used in decision trees:
 of is:
 |
(5.73) |
 |
(5.74) |
 |
(5.75) |
Intuitively, a node with class distribution  has minimum impurity, whereas a node with a uniform distribution
 has maximum impurity.
A “question”  , with
 possible answers, divides the set
 into the subsets
 .
To assess how well the condition performs, the impurity of the child nodes must be compared with that of the parent node: the greater their difference, the better the selected condition.
Given a metric  that measures impurity, the gain
 is a criterion that can be used to determine the quality of the split:
 |
(5.76) |
 is the number of samples in the parent node and
 is the number of samples in the i-th child node.
When entropy is used as the metric, the gain is known as Information Gain (TSK06).
Decision trees induce algorithms that choose a test condition maximizing the gain .
Since
 is the same for all possible classifiers and
is constant, maximizing the gain is equivalent to minimizing the weighted sum of the impurities of the child nodes:
 |
(5.77) |
is the one that minimizes this quantity.
In the case of binary classifiers, the Gini metric is widely used, since the gain to be minimized reduces to
 |
(5.78) |
 is the number of positive and negative samples that the classifier moves to the left branch and
 is the number of samples in the right branch.
Decision trees fit the training data both very well and very quickly and consequently, if not constrained, systematically suffer from overfitting. A refinement algorithm (pruning) is normally applied to trees to reduce, wherever possible, the problem of overfitting. There are usually two pruning approaches: pre-pruning and post-pruning. Pre-pruning stops tree growth under specified conditions to avoid excessive specialization, for example, by limiting the maximum tree size. Post-pruning, on the other hand, refines an already created tree by removing branches that do not satisfy certain conditions on a previously selected validation set.
This tree-construction technique is usually referred to as Classification and regression trees (CART) (B$^+$84). In fact, in the real-valued case, where the analyzed features are statistical quantities, one does not speak of creating a classification tree but, more precisely, of constructing a regression tree. Finding the optimal partition of the data is an NP-complete problem, so greedy algorithms such as the one shown in the section are normally used.
Paolo medici