


Next: Iteratively Reweighted Least Squares Up: Regression and Optimization Methods Previous: Logistic Regression
The use of least-squares regression (Least squares) of the error rather than other weighting functions is motivated both by the maximum-likelihood function and, above all, by the simplicity of the derivatives obtained in the Jacobian.
In the problems considered so far, the variance has almost always been assumed to be constant, with observation errors distributed according to a normal distribution. If the noise were purely Gaussian, this approach would be theoretically correct. However, real applications generally involve distributions consisting of Gaussian noise associated with the model and noise associated with elements that do not belong to the model itself (outliers). Under these conditions, least-squares regression treats all points as if their errors were Gaussian: points close to the model are assigned little weight, whereas points far from the model are assigned substantial weight and, purely on probabilistic grounds, are usually outliers.
A unified way of dealing with these problems was introduced by John Nelder, who named these techniques generalized linear models (GLM, General Linear Models).
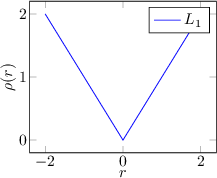
To solve this problem, the metric used to evaluate the errors must be changed: an initial example of a different metric that could solve the problem is absolute-value regression. However, finding the minimum of the error function expressed as an absolute-value distance (Least absolute deviations regression) is not easy, because its derivative is not continuous and requires iterative optimization techniques; differentiable metrics are preferable in this case.
In 1964, Peter Huber proposed a generalization of the maximum-likelihood minimization concept by introducing M-estimators.
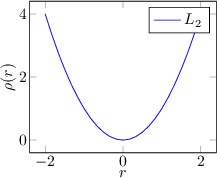
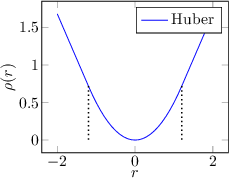
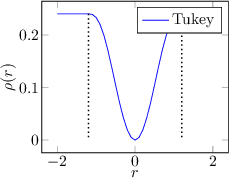
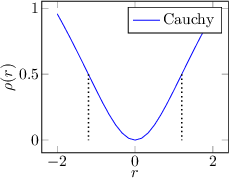
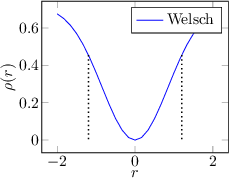
Some examples of regression functions are shown in Figure 4.3.
|
An M-estimator replaces the metric based on the sum of squares with a metric based on a generic  function (loss function) having a unique minimum at zero and subquadratic growth.
M-estimators generalize least-squares regression: setting
 yields the standard form of regression.
Finally, if the loss function is monotonically increasing, it is called an M-estimator; if the loss function increases near zero but decreases far from zero, it is called a redescending M-estimator.
The parameters are estimated by minimizing a sum of generic weighted quantities:
 |
(4.120) |
:
 |
(4.121) |