Next: ZCA Up: Eigenvalue Analysis Previous: Eigenvalue Analysis
Principal Component Analysis, or the discrete Karhunen–Loeve transform KLT, is a technique with two important applications in data analysis:
There are likewise two formulations of the PCA definition:
A practical example of reducing the dimensionality of a problem is the equation of a hyperplane in  dimensions: there exists a basis of the space that transforms the plane equation, reducing it to
 dimensions without losing information, thereby reducing the dimensionality of the problem by one.
Let
 random vectors represent the results of an experiment, that is, realizations of a zero-mean random variable. They can be stored in the rows2.2 of the matrix
 of dimensions
 . Thus, the matrix stores
 random vectors of dimensionality with
 .
Each row corresponds to a different result
 , and the distribution of these experiments must have zero mean, at least empirically.
Assuming that the points have zero mean (which can always be achieved simply by subtracting the centroid), the covariance of the occurrences of is given by
 |
(2.69) |
are correlated, the covariance matrix
 is not diagonal.
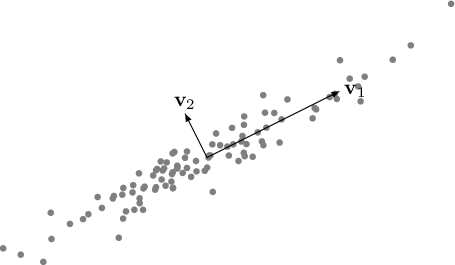
The goal of PCA is to find an optimal transformation  that transforms correlated data into uncorrelated data
 |
(2.70) |
If there exists an orthonormal basis such that the covariance matrix of
 expressed in this basis is diagonal, then the axes of this new basis are called the principal components of
(or of the distribution of
 ).
When a covariance matrix has all its elements equal to
 except on the diagonal, this means that the events are uncorrelated in this new basis of the space.
This transformation can be found by solving an eigenvalue problem: it can be shown that the elements of the diagonal correlation matrix must be the eigenvalues of  , and for this reason the variances of the projection of vector onto the principal components are the eigenvalues themselves:
is the eigenvector matrix (orthogonal matrix
 ) and
 is the diagonal matrix of the eigenvalues
 .
There are two approaches to obtaining this result.
Since
is a real, symmetric, positive-definite matrix, it can be decomposed as
is an orthonormal matrix, the right eigenvalues of
, and
is the diagonal matrix containing the eigenvalues. Since matrix
is positive definite, all its eigenvalues are positive or zero. Right-multiplying equation (2.72) by shows that it is exactly the solution to problem (2.71).
This technique, however, requires the explicit computation of
.
Given a rectangular matrix , the SVD technique makes it possible to find exactly the eigenvalues and eigenvectors of matrix
 , that is, of
, and is therefore the most efficient and numerically stable technique for obtaining this result.
Using the SVD, the event matrix can be decomposed so that

 are the left singular vectors,
 are the eigenvalues of
, and are the right singular vectors.
It should be noted that, when using the SVD, it is not necessary to compute the covariance matrix
explicitly. This matrix can nevertheless be recovered afterward using the equation
 |
(2.73) |
 .
The properties of eigenvalues should be recalled:
 and
are the same.
, that is, the covariance matrix;
 approximation closest to .
This fact, together with the intrinsic property of the SVD of returning the singular values of in descending order, makes it possible to approximate a matrix by one of lower rank.
By selecting the number of eigenvectors with sufficiently large eigenvalues, it is possible to create an orthonormal basis  of space
 such that
 obtained as the projection

rather than , and vice versa.