


Next: 3D Gaussian Splatting Up: Reconstruction, Representation, and Rendering Previous: Rendering
Traditional methods based on meshes or point clouds require an explicit representation of geometry and generally separate geometry from the appearance model. This can make it more difficult to represent view-dependent phenomena such as specular reflections and transparency. To overcome these limitations, Neural Radiance Fields, or NeRFs, introduce an implicit and continuous representation of the scene, in which geometry and visual appearance are encoded implicitly in the weights of a deep neural network, typically a multilayer perceptron (MLP).
Formally, a neural radiance field maps a three-dimensional spatial position
 and a unit viewing direction
 to a volume density
 and an RGB color
 :
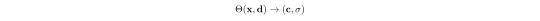 |
(10.115) |
 represents the local attenuation or extinction coefficient of the radiation.
High values of indicate regions of space in which the radiation is more strongly attenuated along its path, thereby implicitly defining the scene geometry.
 represents the RGB radiance associated with the position
 and viewing direction
 , allowing view-dependent phenomena to be modeled.
This representation is trained through differentiable optimization (inverse rendering): starting from a set of calibrated images acquired from different viewpoints, optical rays are projected virtually into the scene and sampled. The final pixel color is computed by integrating the samples along the ray using the volumetric rendering model described in the preceding section. The error between the rendered pixels and the real images is then backpropagated through the network to continuously refine the scene geometry and appearance.
Paolo medici